A token pov through MSAR
Visualising the MSAR architecure from a token focuse prespective, emphasizing the convulution across the sequence dimension.
Visualization · Visualize the core idea
by  ohad · October 31, 2026 · edit this page
 The original
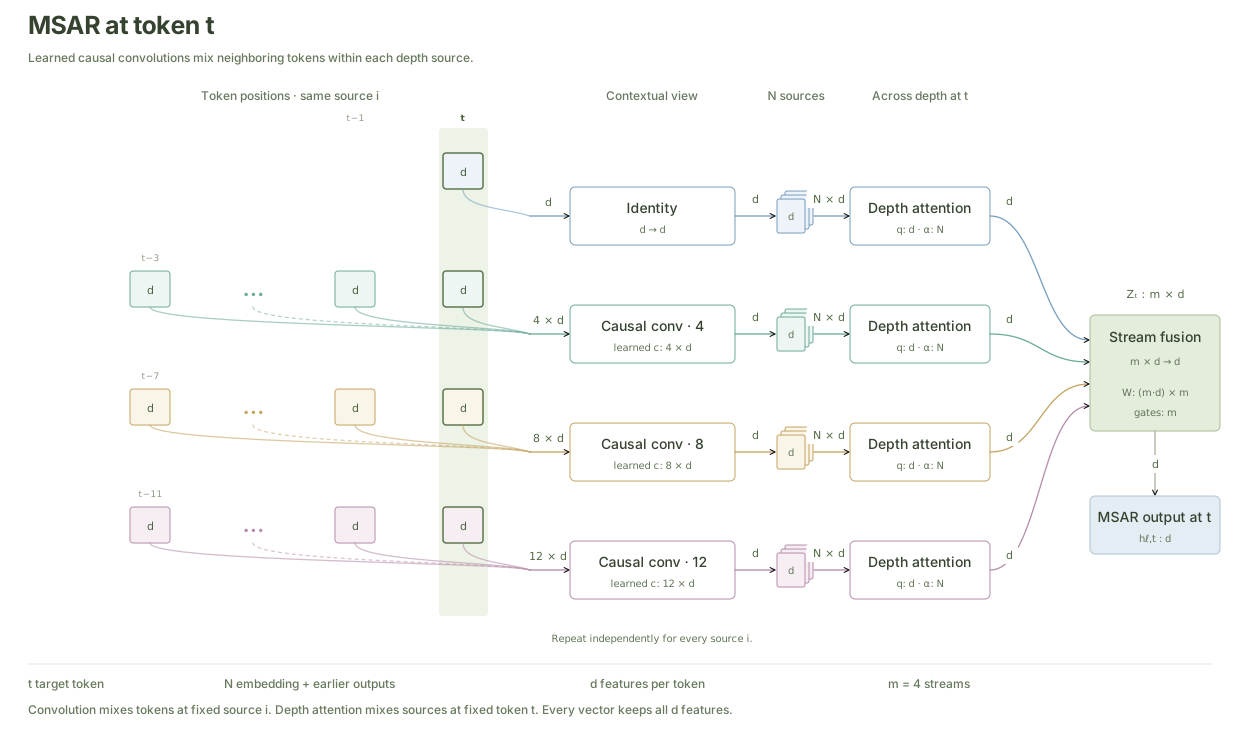
The original figure shows an abstract view of individual components, each activating on the sequence matrix, compared against AttnRes. For an unsuspecting reader, it might seem that the architectures are similar, and that MSAR is simply AttnRes but “more times”. This however is not the case, as the casual convolutions work along the sequence dimension rather then depth.
The redesign
What changed and why
The redesign is essentially a zoom-in of the original. Maintaining every component whilst emphasising the sequence-dimension activations.
Enjoy Reading This Article?
Here are some more articles you might like to read next: